What we do
Any public website, any scale
Give us a target site and requirements. We extract, clean, and deliver structured data on a schedule you define — no infrastructure needed on your side
We handle the hard parts
Anti-bot bypass, CAPTCHA solving, browser fingerprinting, JavaScript rendering, proxy rotation, and schema design — all managed by our team
Delivered to your pipeline
Real-time API, scheduled files, or webhooks. Data lands in S3, GCS, SFTP, or your destination of choice — on the cadence you need
Dedicated account manager
A named person on every project. They handle onboarding, monitor delivery, and respond to issues the same day
How it works
1
Tell us your requirements
Target sites, data fields, delivery format, and refresh frequency. A 20-minute call is usually enough to scope.
2
We build and test
Our team builds the extractors, validates against your schema, and delivers a sample for your approval before going live.
3
Data arrives on schedule
Continuous delivery with monitoring. Your dedicated account manager handles any site changes or issues.
B2B & Sales
AI SDR Platforms
People and company data for automated prospecting, personalisation, and AI-driven outreach sequences
Sales Intelligence
LinkedIn profiles and company data as a full enrichment layer for account intelligence and CRM tools
AI Recruiting Platforms
Candidate profile data for sourcing engines, skills-based matching, and AI-powered recruiting tools
AI & Model Training
Training data, RAG pipelines, and agent enrichment. Schema-consistent records ready for ingestion
Creator & Influencer
Influencer Marketing Platforms
Creator discovery, audience analytics, and campaign management tools built on YouTube, TikTok, and Instagram data
Creator Discovery Tools
Search and filter 200M+ YouTube channels and 100M+ TikTok profiles by niche, follower tier, engagement, and location
Creator Intelligence
Engagement benchmarks, subscriber growth trends, SEO scores, and contact emails across all major platforms
Travel Intelligence
Rate Parity Monitoring
Track hotel and airline pricing across OTA and direct channels. Detect parity breaches in real time
Competitive Rate Intelligence
Monitor competitor pricing across target routes and properties. Feed directly into revenue management systems
OTA Aggregation
Normalised pricing and availability data across 19+ OTAs and brand sites. One schema, all sources
Reviews Intelligence
Competitive Intelligence
Monitor competitor ratings, review trends, and sentiment shifts across G2, Glassdoor, and Capterra
Voice of Customer
Structured review data for NLP, sentiment modelling, and product intelligence at scale
Employer Intelligence
Track employer sentiment, interview experience, and culture signals across Glassdoor and Clutch
WebAutomation
Pricing
Get started free
Browse all extractors
Reddit Search Results Extractor

Reddit Search Results Extractor

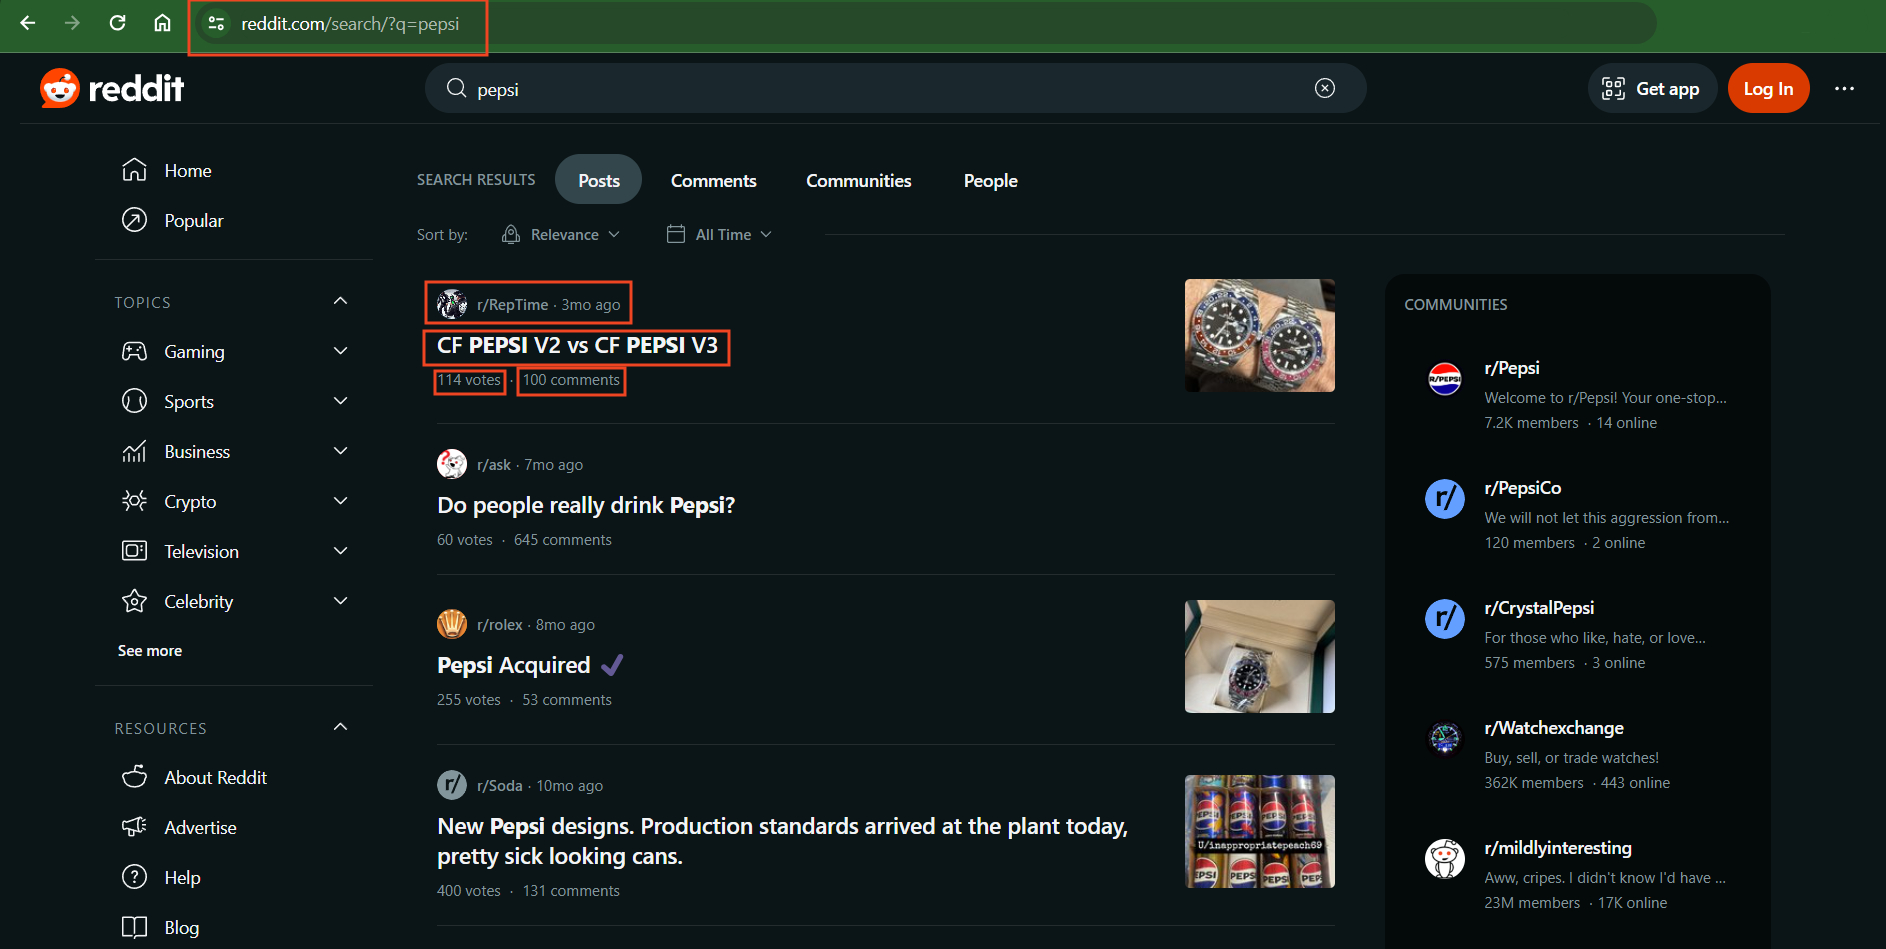
Our pre-built Reddit Scraper extracts all the comments, posts, usernames and votes from search results of keywords made on Reddit.com

Use for free

Our pre-built Reddit Scraper extracts all the comments, posts, usernames and votes from search results of keywords made on Reddit.com

Reddit Search Results Scraper

Our prebuilt reddit.com web scraper lets you extract data including reviews, comments and posts, quickly and easily, from posts made on  reddit.com without having to write any code.

Why scrape reddit.com?

Blogs and forums are a great source of alternate data. Given how diverse and easily accessible blogs are, they are a great source of information, not only for the people reading them but for the person scraping them as well. 

Blogs like reddit.com can help you understand customer sentiment and consumer preferences. 

Active conversations on active blog posts can help you understand upcoming market trends and with enough data, you can even predict the market sentiment towards various topics.

But why use Webautomation.io?

With the amount of being generated on reddit.com every day, it's impossible to go through each of them manually. The data is rapidly changing and always evolving. You need a way to keep up with that change. 

And that’s where our predefined web scrapers come into play. 

These web scrapers have been designed specially to extract data from the reddit.com. Our simple yet powerful tool automates the whole process of extracting data, without having to write any code.

And the best part? Our reddit.com web scraper is completely free to try!

Easy to Use and Free to Try

A few mouse clicks and copy/paste is all that it takes!

* to use you will need to sign up for a  FREE TRIAL account

Steps to use:

Step 1: Click on "use for Free"

Step 2: Activate the Pre-Defined extractor by clicking the "Activate button"

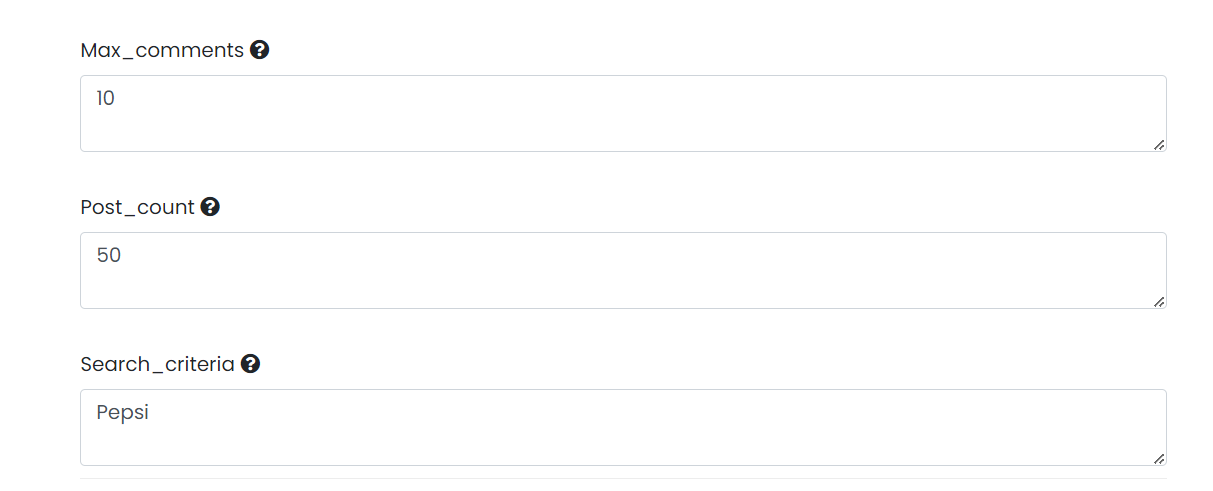
Step 3: Click on the "input" tab and enter a search criteria you would like to scrape from Extractor Variables by clicking the plus button. You can also choose the maximum number of comments and post counts you'd like to scrape from here.

Step 4: Click "Run now" 
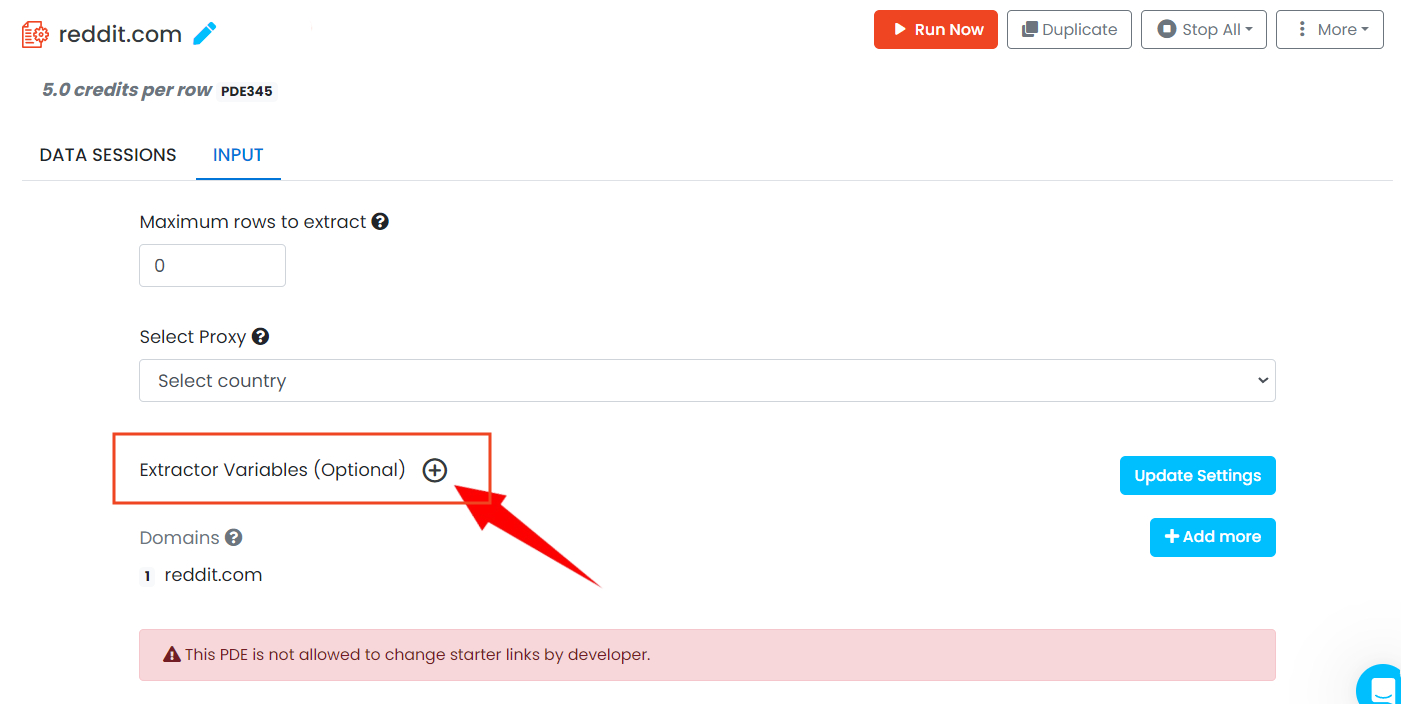
Using this extractor, you can get:

  • author
  • author id
  • comments
  • date
  • domain
  • link
  • number of comments
  • source
  • subreddit
  • text
  • title
  • votes
  • post id


Video tutorial

Watch how I quickly use the tool to extract data from reddit.com


Cost

When you use Reddit Search Results Extractor pre-defined web scraper, the cost will be 5 credits per row which equals to $1 for 200 rows.


The output file can be exported as csv, xml, xlsx, json formats.

Below is a screenshot of what data fields we will be web scraping from Reddit.com


You will get your data in following structure in different formats:

{
 "post_id":"t3_18ja20h",
"Link":"https://www.reddit.com/r/Damnthatsinteresting/comments/18ja20h/pepsi_vs_coke_ants_preference/",
"Domain":"v.redd.it",
"Author":"android_pancake",
"Author_id":"t2_3xauh2cy",
"Number_of_comments":2144,
"Title":"Pepsi vs coke, ants preference ",
"Date":{"year":"2023","month":"12","day":"15","hour":"21:56"},
"Votes":58302,"Source":{},
"Subreddit":"Damnthatsinteresting",
"Text":"Video",
"Comments":[{
"Author":"International-Dig864",
"Author_Id":"t2_al7cdcbk",
"comment_id":"t1_kdixs6r",
"comment_text":"Now repeat the experiment"
}
 

What does the output data look like?

*** Data below was extracted on May 28, 2026 @17:00

Modified
2 years, 7 months ago
Last test
4 months, 2 weeks ago
Used
660 time(s)
Used by
250 user(s)
USE FOR FREE
Benefits
  • No programming required: Get data like an expert without any coding knowledge
  • Runs on the cloud: No need to download any software or extensions
  • ​On-demand support: We are ready to help or make changes to the scrapers as required
  • ​Extract data on a schedule: Automate your Amazon extractor to run weekly, daily and even hourly
  • ​No Maintenance: We monitor and resolve any issues relating to website structure changes and blocking from website

Requirements

To be able to use reddit search results scraper, your account must have the requirements below. If you satisfy the conditions the data output of your scraper will be one click away.

At least basic subscription plan.
At least 1$ credit in the balance

Any question? We'll help you out

Ask about webautomation products, pricing, implementation, or anything else. Our knowledgeable reps are standing by, ready to help.